Heavy equipment engineering for reliability, safety and lifecycle performance
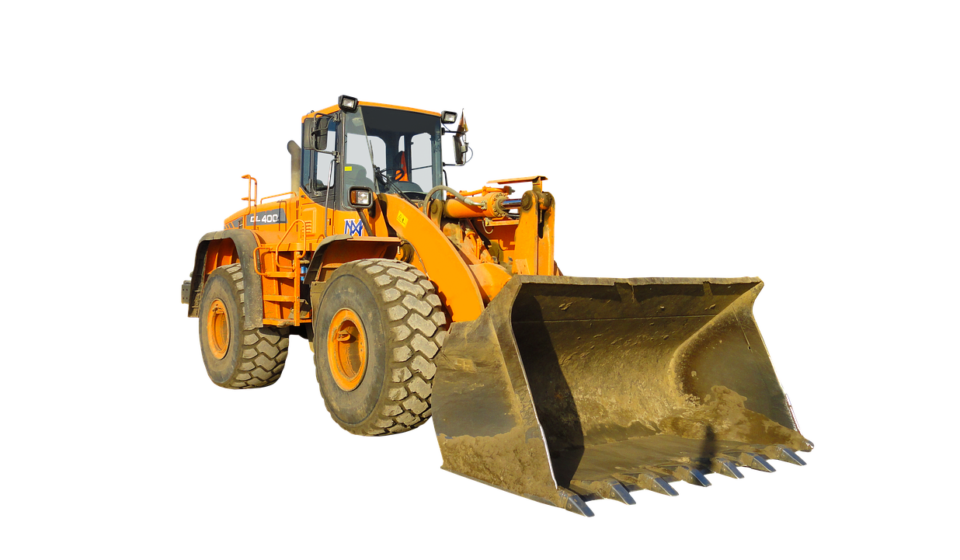
Heavy equipment engineering is the discipline of making large machines—excavators, haul trucks, cranes, loaders, presses, conveyors and other high-value assets—reliable, safe and economically defensible over time. For industrial operators, the question is not simply whether a machine can perform a task. It is whether the machine can keep performing that task under load, in harsh environments and with controlled risk throughout its service life.
Good engineering connects design requirements, maintainability, operator safety, asset data and replacement decisions. It also keeps maintenance from becoming an afterthought. This article outlines how reliability teams can structure that work across the equipment lifecycle.
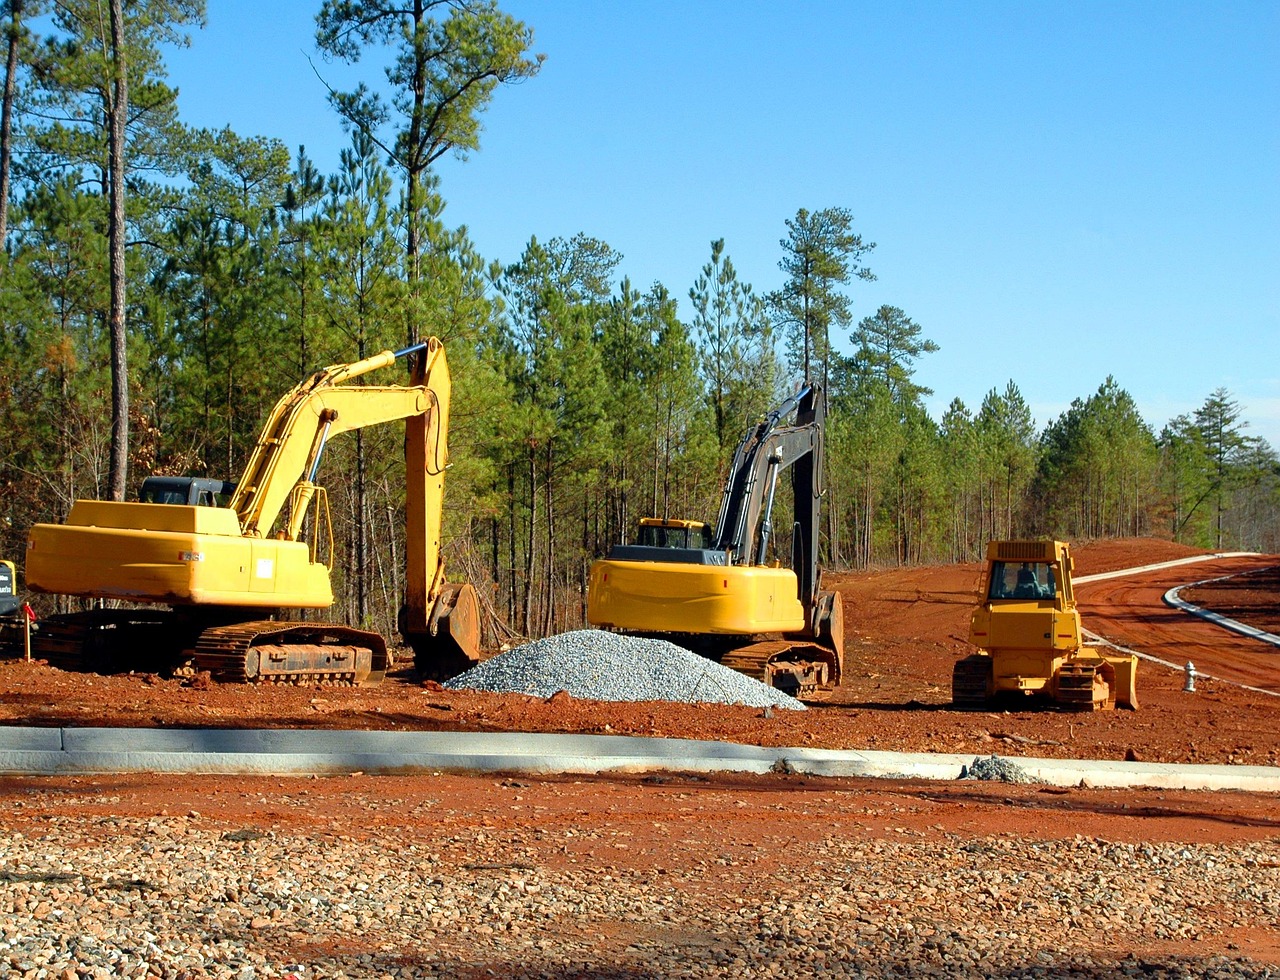
What heavy equipment engineering covers
Heavy equipment engineering sits across mechanical design, electrical and hydraulic systems, controls, maintenance planning, safety management and asset management. In an original equipment manufacturer context, it may focus on structural strength, powertrain selection, hydraulic architecture, braking systems, guarding, ergonomics and software-controlled functions. In an owner-operator context, it usually means selecting, modifying, maintaining and replacing equipment so production needs are met with acceptable cost and risk.
The reliability perspective matters because heavy equipment failures are expensive, disruptive and sometimes dangerous. A failed shovel, mobile crane, crusher or haul truck can stop a production chain, create recovery work in a hazardous location, consume scarce spare parts or expose technicians to stored energy. That is why reliability engineering for heavy assets must look beyond mean time between failures. It has to consider consequence, detectability, maintainability, operating context and the quality of decisions made across the asset life cycle.
Public standards help frame this work. ISO 55000:2024 describes asset management vocabulary, principles and an overarching framework for realising value from assets. ISO 14224:2016, although written for petroleum, petrochemical and natural gas industries, is a useful reference for structured reliability and maintenance data. These references do not replace site-specific engineering judgment, but they do support a disciplined language for classifying assets, failures and maintenance actions.
Reliability starts with asset requirements
Many heavy equipment reliability problems begin before the machine is installed, commissioned or dispatched. If the specified machine is mismatched to the duty cycle, environment or maintenance capability, the reliability team inherits a problem that inspection alone cannot solve. Requirements should define the work to be done, the production window, the operating environment, the support model and the acceptable risk profile.
Duty cycle and environment
Duty cycle is more than annual operating hours. It includes load variation, shock loading, idle time, travel distance, start-stop frequency, grade, ambient temperature, dust, vibration, moisture, corrosive exposure and operator practice. A wheel loader in a quarry, a crane at a congested construction site and a press line in a factory may all be classified as heavy equipment, but their dominant failure drivers are different. Engineering teams should capture those differences in specifications and maintenance plans rather than relying only on generic intervals.
Maintainability and access
Maintainability should be designed and verified, not assumed. Filters, grease points, inspection covers, isolation points, sensors, wear components and diagnostic ports should be accessible without excessive disassembly or unsafe body positioning. A component that is technically reliable but difficult to inspect may still increase risk because defects remain hidden until failure. Likewise, a maintenance task that takes too long may be skipped, deferred or performed under pressure.
A practical reliability review should ask: Can the component be inspected while the equipment is safely isolated? Are special tools required? Are lifting points clearly identified? Can technicians confirm zero energy before working? Are replacement parts modular enough to reduce downtime? These questions turn reliability from an abstract performance measure into a design and work-execution requirement.
Build the data foundation before choosing technology
Modern fleets often generate telematics, fault codes, sensor readings and maintenance records. More data, however, does not automatically lead to better decisions. The first requirement is a clean asset hierarchy and a consistent failure language. Without those basics, dashboards may show activity rather than real reliability improvement.
| Data element | Why it matters | Common weakness |
|---|---|---|
| Asset hierarchy | Connects failures to the right machine, system and component | Inconsistent names across maintenance, finance and operations |
| Operating hours or cycles | Normalises failure and cost rates | Missing meter readings or mixed hour, mile and cycle measures |
| Failure mode | Shows how an asset failed, not only that it stopped | Overuse of vague codes such as “broken” or “other” |
| Work order history | Links symptoms, actions, labour, parts and downtime | Closed orders with little technical detail |
| Condition data | Supports trend-based intervention before functional failure | Alarms not linked to decisions or response rules |
ISO 14224:2016 is valuable here because it emphasises the structured collection and exchange of reliability and maintenance data during the operational life cycle of equipment. Even when a site is outside the industries named in that standard, the underlying logic remains useful: define the equipment boundary, classify failures consistently, record maintenance actions and preserve operating context.
Condition monitoring should be selected around failure modes. Vibration analysis may be useful for rotating machinery, oil analysis for engines and gearboxes, thermal imaging for electrical and mechanical heat patterns, pressure trends for hydraulic systems, and payload or duty-cycle data for mobile fleets. Predictive analytics can help, but only when the monitored variable has a credible relationship to a failure mechanism and when the organisation can act on the warning.
Choosing the right maintenance strategy
Heavy equipment does not need one maintenance philosophy. It needs a mix of strategies based on risk, failure behaviour, detectability and economics. The wrong strategy can waste labour, consume parts too early or allow avoidable failures to occur.
Preventive maintenance
Preventive maintenance is appropriate when time-based or usage-based actions reduce the probability of failure. Examples include lubrication, filter changes, torque checks, calibration, safety device inspections and scheduled replacement of known wear items. The interval should be based on manufacturer recommendations, operating severity, history and regulatory requirements where applicable. If a task repeatedly finds no degradation, the interval may be too conservative. If failures occur before the interval, it may be too long or the task may be targeting the wrong failure mode.
Condition-based maintenance
Condition-based maintenance is useful when degradation can be detected before functional failure. It is often a strong fit for hydraulic contamination, bearing wear, gearbox condition, brake temperature, engine health and structural cracking inspections. The key is to define thresholds, response times and ownership. A sensor alert that no one owns is not a maintenance strategy.
Run-to-failure
Run-to-failure is not automatically poor practice. It may be suitable for low-cost, non-critical items with no safety consequence and easy replacement. It is not suitable for components whose failure can create a serious safety hazard, extended outage, collateral damage or environmental release. The reliability team should document the reason for allowing run-to-failure so the decision is intentional, not the result of neglect. See also: automation and controls.
Predictive maintenance
Predictive maintenance uses data patterns to forecast or identify developing faults. Its value depends on data quality, failure history, model transparency and response capability. A site should avoid buying predictive tools before it can answer basic questions: Which failures are being predicted? What lead time is needed? What action follows an alert? How will false alarms and missed detections be reviewed?
Safety and regulatory constraints are reliability requirements
In heavy equipment engineering, safety is not separate from reliability. A machine that fails unpredictably can create struck-by, caught-between, rollover, lifting, stored-energy, fire or electrical hazards. OSHA construction guidance has described a large share of struck-by fatalities as involving heavy equipment such as trucks or cranes. That point matters even outside construction because it shows how equipment reliability, visibility, traffic control, braking, alarms and operator procedures interact.
Safety-critical systems need stricter change control than ordinary comfort or productivity features. Brakes, steering, lifting mechanisms, interlocks, guards, overload protection, emergency stops, proximity detection and control software should be managed with clear inspection criteria and documented repair standards. Modifications should be reviewed for unintended consequences. Adding weight, changing attachments, altering hydraulic settings or bypassing an interlock can change the risk profile of the machine.
For organisations placing machinery on the European Union market, Regulation (EU) 2023/1230 is also relevant because its main application date is 20 January 2027, with some provisions applying earlier. The practical message for reliability and engineering teams is not to treat compliance as a paperwork exercise. Technical documentation, risk assessment, instructions, conformity requirements and safety-related design choices can influence maintenance, spare parts, upgrades and future modifications.
Regulations and standards set minimum expectations, but site-specific controls still matter. Traffic plans, exclusion zones, lockout and isolation procedures, operator competency, maintenance access and incident learning should be built into the asset management system. A reliable machine in an uncontrolled work environment can still be unsafe.
Lifecycle decisions should balance cost, risk and performance
Heavy equipment decisions are often distorted by the purchase price. A cheaper machine may become expensive if it has poor fuel efficiency, weak parts availability, difficult maintenance access, low resale value or frequent unplanned downtime. Conversely, replacing an older asset too early can waste capital if the machine still meets performance and risk requirements.
Lifecycle analysis should include acquisition cost, commissioning, operator training, fuel or energy consumption, planned maintenance, corrective maintenance, downtime, parts logistics, attachments, compliance upgrades, residual value and disposal. For mobile fleets, tyre or track costs, haul road condition, idle time and payload discipline may be major economic drivers. For fixed heavy equipment, foundations, alignment, utilities, structural fatigue and upstream or downstream production constraints may dominate.
A useful replacement review combines facts and judgment. The facts include availability, maintenance cost per operating hour, repeat failures, safety incidents, inspection findings, emissions or regulatory limits, parts lead times and backlog. Judgment is needed to interpret whether the trend is reversible. If downtime is caused by poor planning or weak lubrication discipline, replacing the machine may hide the real issue. If the asset has structural fatigue, obsolete controls and rising parts risk, continued repair may be false economy.
Reliability teams can use a staged roadmap. First, create a criticality ranking so attention goes to assets with the highest production and safety consequences. Second, clean the asset register and failure codes. Third, review maintenance plans against known failure modes. Fourth, improve work quality through standard procedures, isolation practices and closeout notes. Fifth, add condition monitoring where it clearly supports a decision. Finally, review capital replacement with lifecycle evidence rather than opinion alone.
Frequently asked questions
Is heavy equipment engineering the same as maintenance?
No. Maintenance is one part of heavy equipment engineering, but the engineering scope is broader. It includes specification, design review, reliability analysis, maintainability, safety controls, data structure, operating context, modification control and replacement planning.
What data should a reliability team collect first?
Start with the asset hierarchy, operating hours or cycles, work order history, failure modes, parts used, downtime and safety-related findings. These basics make later condition monitoring and analytics more useful because they connect symptoms to assets, causes and consequences.
When is predictive maintenance worth using?
Predictive maintenance is worth considering when a failure mode is expensive or hazardous, degradation can be detected early, the data is trustworthy and the organisation can act before failure. It is less useful when failures are random, low consequence or not linked to measurable signals.
How should teams decide whether to repair or replace heavy equipment?
The decision should compare lifecycle cost, reliability trend, safety risk, parts availability, compliance exposure, production impact and residual value. A replacement case is stronger when failure risk is rising for reasons that maintenance cannot economically reverse.